Digest — 2026-10-09
No stories match the selected filters.
nullmoth/nvidia-macos-driver
Apple dropped NVIDIA GPU support in macOS years ago, so building a working Metal driver for RTX cards on Sequoia via Hackintosh-style OpenCore setups is a substantial reverse-engineering effort. Writing GPU drivers, especially translating to Apple's Metal API, requires deep knowledge of both the hardware's command submission model and Apple's graphics stack. This is the kind of low-level systems work that is rare and technically impressive regardless of practical mainstream need. The project being written in Rust and fully open source adds further technical interest for systems programmers.AI-analyzed
 must readgithubRepoA genuinely hard and niche engineering feat, writing a working Metal graphics driver for unsupported NVIDIA GPUs on modern macOS.
Decoupling Exploration from Optimization in RLVR
The paper tackles a known problem in reinforcement learning with verifiable rewards, where encouraging a model to explore novel reasoning paths often degrades its overall quality. Their fix trains separate explorer models with a novelty bonus, filters their outputs for correctness, then distills the good ones into a clean student model trained without that novelty pressure. This decoupling lets them scale up exploration aggressively without the usual quality collapse, and they show better results than a strong baseline across seven math benchmarks. This is a practically useful training recipe for anyone building reasoning-focused LLMs via RL.AI-analyzed
 recommendedarxiv~1 min readA clever architectural idea for improving reinforcement learning in LLMs by separating exploration from the final optimized model.
openai/math
This repository uses Lean, a language for writing machine-checked mathematical proofs, suggesting it relates to formal math or AI math-reasoning research. Given OpenAI's recent public work on AI systems solving olympiad-level and research-level math problems, this is likely connected to that effort, perhaps as a benchmark, proof library, or verification toolkit. The high star count signals strong community interest, likely from both the formal-methods and AI research communities. Worth checking out for anyone tracking the intersection of LLMs and formally verified mathematics.AI-analyzed
recommendedgithubRepoA formal mathematics repository from OpenAI using the Lean proof assistant, likely of real interest to people working on formal verification and AI-assisted theorem proving.Whistle: Speech to Text in 16.9 MB
Whistle appears to be a very small speech recognition model, around 17 megabytes, small enough to run on constrained devices. If accuracy holds up, this matters because most speech-to-text systems are large and need cloud inference or beefy hardware. Shrinking models to this size usually involves aggressive quantization or distillation tricks worth understanding. The high comment count suggests people are actively testing and comparing it against alternatives like Whisper.AI-analyzed
recommendedhnDiscussion512 pointsA tiny, locally runnable speech-to-text model is practically useful and technically interesting for edge/embedded applications.Discuss →
Long-WAM: Scaling the Context of World-Action Models
Long-WAM studies how much past visual context a robot control model needs to act well, and finds that simply having more history only helps if the underlying video model was trained in a causal, autoregressive way. Using that insight, they show success rates jumping substantially, from 63.3% to 78.7%, as context length increases on a benchmark called RoboCasa GR-1. They also engineered the system to run in real time on actual edge GPUs, reporting 107.4 milliseconds per action chunk, and demonstrated clearly superior performance on a dynamic cup-stacking task compared to other named baselines. This combination of a clear empirical insight plus real hardware deployment numbers makes it a solid applied robotics contribution.AI-analyzed
recommendedarxiv~1 min readA systems-and-modeling paper on giving robot control models longer visual memory in real time, with concrete deployment numbers on real hardware.EngramEdit: Decoupled Knowledge Updates in LLMs through Conditional Memory
EngramEdit builds on conditional memory architectures that store facts in lookup tables keyed by word sequences, separate from the model's general reasoning weights. The core challenge they solve is that the same fact can be phrased many ways, each potentially hitting different memory entries, so naive edits either miss some phrasings or corrupt unrelated facts. Their method computes target representations across multiple phrasings and updates shared entries carefully, weighting against frequently reused ones to limit collateral damage. The reported near-perfect editing success and preserved unrelated knowledge make this a concrete advance in making LLMs updatable after deployment.AI-analyzed
recommendedarxiv~1 min readA technically detailed method for editing specific facts inside a large language model without full retraining, relevant to knowledge-editing research.Never Look Back: Understanding Persistence in 3D Object Memory from Egocentric Videos
This paper builds a system called Ledger that lets a robot or AI assistant remember where objects are and what happened to them, even after they leave the camera's view. It clusters repeated observations to filter out noise and keeps short text descriptions so questions can be answered without re-watching video. The reported gains, such as raising accuracy from 29.7% to 42.6% on one benchmark, are substantial and suggest real improvement over naive baselines. This is a meaningful step toward embodied AI assistants with longer-term spatial memory rather than just reacting to the current frame.AI-analyzed
recommendedarxiv~1 min readA solid robotics/computer vision paper on building persistent object memory from first-person video, relevant to embodied AI research.
How React Actually Works Under the Hood (And Why Your Mental Model Might Be Wrong)
The article walks through the common confusion where a React state variable logs its old value immediately after being updated, because state updates are batched and applied on the next render rather than instantly. It promises to go beyond the superficial 'setState is asynchronous' explanation and dig into React's actual internal data structure, the Fiber tree, and how hooks rules stem from it. This kind of under-the-hood explainer is genuinely useful for developers who want to move past surface-level React usage to understanding its rendering model. The quality depends on how deep and accurate the Fiber tree explanation actually gets, which cannot be fully judged from the excerpt alone.AI-analyzed

To Retry or Not to Retry? That Is the Question.
The author builds a benchmark around a narrow but practically important question: whether language models can correctly reason about retry safety for failed HTTP requests given status codes, idempotency keys, and timing. This is a genuinely subtle distributed systems problem, since naive retries can cause duplicate processing of POST requests or mask real failures. Framing an LLM evaluation around this kind of nuanced, real-world engineering judgment call is more interesting than generic coding benchmarks. The piece seems to combine solid systems knowledge with a reasonable evaluation methodology.AI-analyzed

The September cut took 17% of my Claude Code week. Subagents were taking 48%.
The author analyzed their own actual usage logs, 455 sessions and 63,000 requests, to figure out why their weekly AI coding quota was running out faster after a service change. They found that subagents, helper processes spawned to do subtasks, were consuming a much larger share of tokens than the user's own direct interactions. They also caught and corrected a double-counting bug in the raw logs that would have overstated token usage by roughly double. This is a concrete, reproducible-methodology piece of real operational data about a widely used AI coding tool, which is genuinely useful for other heavy users trying to manage cost and quota.AI-analyzed
 recommendeddevto~1 min excerptA detailed, data-driven dissection of how AI coding agent subagents consume disproportionate usage quota, useful for heavy Claude Code users optimizing cost and workflow.
Why isn't the industry freaking out about DeepSeek 4.1 Flash?
This piece questions why a new DeepSeek model variant has not caused more industry reaction despite apparently strong performance or cost advantages. It is likely more opinion and discussion than hard technical detail, given the discourse-style title. Still, the comment volume suggests substantive back and forth over benchmarks, pricing, or model behavior. Worth skimming for competitive-landscape context on open versus closed model releases.AI-analyzed
Decentralized SGD under Heavy-Tailed Noise: Optimal Convergence Rates and the Role of Gradient Clipping
The paper addresses a fairly specific but important theoretical question: whether decentralized stochastic gradient descent with gradient clipping can achieve optimal convergence rates when noise does not behave nicely, i.e. has heavy tails. They show mathematically that clipped decentralized SGD does achieve order-optimal rates and even benefits from adding more agents, something not previously shown for clipping-based decentralized methods. The key technical contribution is a sharper analysis of how much nodes disagree with each other during training, isolating network effects as a secondary concern. This is a solid theoretical result but speaks mainly to researchers working on distributed optimization theory rather than practitioners.AI-analyzed
notablearxiv~1 min readA theoretical optimization paper proving convergence guarantees for gradient clipping in decentralized SGD under heavy-tailed noise, mainly of interest to optimization researchers.
I got Jev to zero mistakes. I'm still using Flash-Lite.
The author compares a new small 'decision model' called Jev against Google's Gemini Flash-Lite for a classification-style task that returns calibrated probabilities over fixed options rather than free text. Instead of relying on hype, they ran both on real production data thousands of times and measured actual performance and cost, which is a credible way to evaluate model claims. It is a useful case study in picking the right-sized model for a narrow task rather than defaulting to whatever is trending. The piece is grounded in a real evaluation harness (benchspec) which adds some concrete methodology to back the claims.AI-analyzed
notabledevto~1 min excerptA practical, data-driven comparison of a new hyped lightweight model against a cheaper incumbent for a real production decision task.
Man discovers his parents' coffee machine used 1TB of data in 10 days
The story describes a smart coffee machine quietly consuming a terabyte of data in just ten days, which is a real anomaly worth diagnosing. It likely touches on topics like excessive polling, misconfigured cloud sync, or chatty IoT firmware that engineers building connected devices should care about. It is a lighter, human-interest technical story rather than deep engineering content, but the root cause analysis could be genuinely instructive. Good cautionary tale about IoT telemetry design.AI-analyzed
notablehnDiscussion370 pointsA concrete and slightly absurd story about embedded device telemetry gone wrong, interesting for IoT/networking engineers.Discuss →
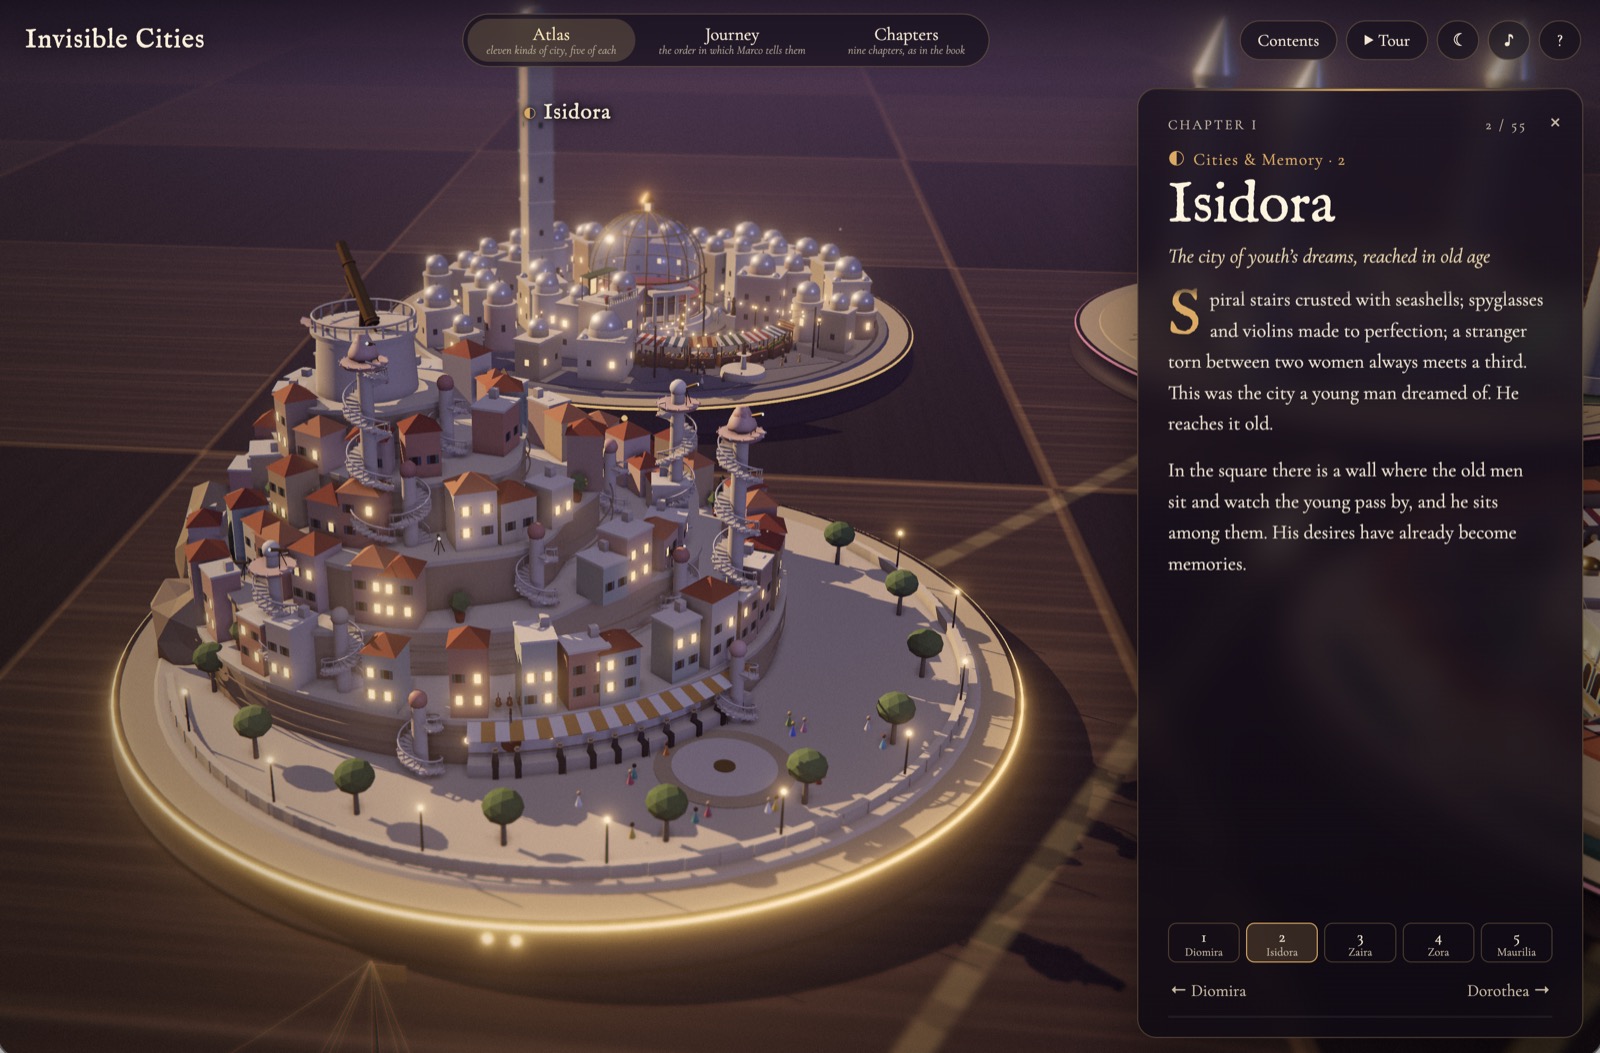
I gave Opus 5.5 one prompt and six hours to visualize Invisible Cities
This is an experiment giving a large AI model, apparently a recent Opus version, an open-ended creative task over an extended run time to visualize a literary work. It is a capability-probing exercise rather than rigorous benchmarking, so conclusions are anecdotal. Still, long-horizon unsupervised generation tasks like this reveal interesting things about model planning, consistency, and failure modes over time. Likely of interest to people tracking what frontier models can autonomously produce.AI-analyzed
notablehnDiscussion354 pointsAn exploratory look at a frontier AI model's long-form generative and visualization capabilities, interesting as an AI capability demo.Discuss →
alchaincyf/huashu-art-motion
This project appears to be a Chinese-language 'skill' package offering 35 artistic animation styles and nine narration grammars, letting users turn static images or ideas into animated content through code. It likely targets creative coding, generative art, or video content automation workflows. Without more detail on the underlying techniques, it reads more like a curated template library than a novel technical contribution. Of niche interest to those doing generative art or short-form video automation.AI-analyzed
notablegithubRepoA code-driven animation toolkit covering many artistic styles, interesting mainly to creative coders rather than general software engineers.Jakeschincariol/replica-skill
This repository packages prompts or workflows for Claude-based agents to reverse-engineer, rebuild, test, and iterate on existing applications. Technically, it is an interesting demonstration of agentic workflows applied to software reverse engineering and iterative development. However, 'clone any app' framing raises concerns about intellectual property and competitive cloning, though the tool itself is a general-purpose automation framework rather than inherently malicious. It's a borderline case worth including but flagged for its ambiguous real-world use.AI-analyzed
notablegithubRepoA set of AI agent skills for cloning apps raises both practical interest and ethical questions depending on how it's used.I hired an illustrator to draw my house. Now it's my Home Assistant dashboard
This is a home automation hobby project where someone commissioned custom artwork of their house to use as an interactive dashboard background. It is creative and well-executed but represents a niche, cosmetic use case rather than a technical breakthrough. There may be some useful detail on how they wired illustration regions to live Home Assistant entity states. Mostly appeals to smart-home enthusiasts and UI tinkerers.AI-analyzed
kargulstudio/sales-crm
This is a sales CRM built in TypeScript, which is a common and well-trodden application category in open source. Without distinguishing architectural or technical features mentioned, it's hard to say what sets it apart from the many existing CRM projects. It may be useful to developers looking for a CRM starting point or learning reference, but it is not groundbreaking. The reasonably high star count suggests decent usability or marketing rather than unique technical merit.AI-analyzed
notablegithubRepoA fairly generic open-source CRM project, useful as a reference implementation but not technically novel.
Every Software Developer Has Blamed…
This piece is a casual, humorous reflection on common things developers blame for problems, like other developers or the company, written after attending a conference. It contains essentially no technical substance, code, or systems analysis. It may resonate as relatable workplace humor but offers nothing new for a technical digest reader. Low value for engineers seeking substantive technical content.AI-analyzed