Digest — 2026-09-18
No stories match the selected filters.

US Military had close call after using AI for hallucinated intelligence report
The story reportedly describes an incident where an AI system generated a fabricated ('hallucinated') intelligence report that was nearly acted upon by the US military, illustrating the danger of deploying generative AI in high-consequence decision pipelines. This matters technically because it highlights a real deployment failure mode, models confidently producing false information, in a domain where verification is hard and the cost of error is severe. It's a useful case study for engineers designing human-in-the-loop safeguards, confidence calibration, or provenance tracking for AI-generated outputs in critical systems.AI-analyzed
recommendedhnDiscussion344 pointsA real-world account of an AI hallucination causing a near-miss in a military intelligence context is a concrete, high-stakes case study of LLM reliability failures.Discuss →
Workspace Models: Lightweight Robotic Memory via Saliency-Driven Supervision
Robots doing complex tasks often need to remember past events, but naively feeding a full history into a policy causes it to latch onto irrelevant patterns and perform worse. Prior fixes query a vision-language model live during operation to filter down to task-relevant history, which is computationally expensive. This paper instead does that expensive filtering only during training, distilling the results into a small learned 'workspace token' that can be reused cheaply at run time, and reports this is both lighter-weight and yields better policy performance than the alternatives, in both simulation and on real hardware.AI-analyzed
 recommendedarxiv~1 min readA robotics memory technique that avoids expensive vision-language model calls at deployment time by distilling task-relevant history into a compact token during training.
Embedding Models Measure in Peculiar Ways
The researchers test whether embedding models, which convert text into vectors meant to capture meaning, correctly represent physical measurement concepts such as mass, distance, time, and volume that have objectively verifiable equivalences. They find embeddings weakly encode true physical relationships and instead are swayed by surface-level string similarity, for example treating '5 km' as similar to '5 miles' because of shared characters rather than actual unit conversion. Attempts to recalibrate similarity scores didn't fix the underlying misalignment. This is a useful negative result for anyone building retrieval or reasoning systems that assume embeddings understand quantities correctly.AI-analyzed
recommendedarxiv~1 min readA focused empirical study showing that text embeddings poorly capture real physical quantities like mass and distance, which matters for anyone using embeddings for reasoning tasks involving measurements.Coding Agents with an Obstacle-Aware Harness for Safe Robot Manipulation
The paper investigates whether coding agents that generate robot control programs from language models actually respect stated safety constraints like avoiding obstacles, finding that they mostly fail to prioritize this despite understanding it. They trace the failure to planning, not perception, since the model reasons about the obstacle but doesn't treat avoidance as a hard constraint during route planning or contact execution. Their fix, SafeHarness, adds explicit obstacle-aware route planning with waypoint verification and replanning, plus contact-position selection that avoids the obstacle, improving task success to 71.9% and collision avoidance to 87.5%, notably better than prior state of the art. This is a useful, concrete contribution to making LLM-based robot control safer rather than just more capable.AI-analyzed
recommendedarxiv~1 min readA concrete, well-defined study of a real safety gap in LLM-driven robot control, with a proposed fix and measurable improvements.Cloudflare Quick Tunnels
Quick Tunnels are Cloudflare's free, no-signup way to expose a local port to the internet via a temporary public URL, commonly used for demos, webhooks, and testing. The topic is a solid piece of everyday developer infrastructure rather than a novel research result. Without more detail (this entry lacks an abstract or article excerpt), the analysis is necessarily about the general feature area rather than specific new claims made in the discussion.AI-analyzed
recommendedhnDiscussion510 pointsCloudflare Quick Tunnels are a widely-used practical tool for exposing local services, and the discussion volume suggests real engineering debate about their reliability or design.Discuss →
Android 17 is the first since 3.x to add new APIs without releasing to the AOSP
The claim is that Android 17 introduces new public APIs without first landing the corresponding code in the open-source AOSP repository, a shift from past practice. This matters because AOSP visibility affects custom ROM developers, security researchers, and companies building Android forks who rely on inspecting implementation code. If accurate, it signals a further tightening of Google's control over the platform's genuinely open portions, which has real downstream effects for the broader Android ecosystem.AI-analyzed
 recommendedhnDiscussion391 pointsA concrete governance change in how Android exposes new APIs is genuinely relevant to Android developers tracking platform openness trends.Discuss →
Paint-Anything: Unified Any-Color Control for Image Generation and Editing
Paint-Anything lets a diffusion image model take a precise 24-bit hex color code and apply it faithfully to a specific object during generation or editing, which prior methods handled only loosely or with specialized machinery. The authors built a large training dataset (Paint-500K) by grounding objects in real photos and labeling their colors, then supplemented it with synthetic 'pure-color anchor' examples to handle cases like shadows that make real photos only approximate the target color. Tested on the FLUX.2-4B model, it substantially improves color-fidelity benchmarks over the base model. This is a useful, if narrow, engineering contribution for professional design tools rather than a fundamental advance in image generation.AI-analyzed
notablearxiv~1 min readA practical image-generation control method letting users specify exact hex color values for objects, useful for design workflows but a narrow, incremental capability.FAMOS: Feed-Forward 3D Articulation Modeling from Sparse Observations
FAMOS predicts which parts of an object can move and how (their joint parameters) using only a handful of point-cloud snapshots, rather than requiring dense scans or per-category shape assumptions. Its key architectural idea, a Multi-state Articulation Transformer, combines information across multiple partial views using attention mechanisms that alternate between per-observation and global reasoning. The authors also built a synthetic data generator to address the shortage of large, varied training datasets for articulated objects. This is a solid, narrow research contribution mainly of interest to people working on robot perception or 3D object modeling rather than general engineers.AI-analyzed
notablearxiv~1 min readA technical advance in reconstructing how objects move (like hinges and joints) from limited camera views, relevant to robotics and 3D vision researchers.tamaratran/fast-jev-compaction
'Compaction' in AI coding assistants refers to summarizing older conversation history to fit within a model's context window as a session grows long. This plugin reportedly replaces the default summary with a scoring system that decides, per tool call and result, whether to keep it verbatim, truncate it, or drop it entirely, aiming to preserve more useful detail than a generic summary would. This is a fairly niche but genuinely useful engineering detail for people building or heavily using long AI coding sessions, since context management quality directly affects agent reliability.AI-analyzed
 notablegithubRepoA plugin for Claude Code that changes how conversation history gets summarized during compaction, a practical detail for engineers using long-running AI coding sessions.
How to Write with an LLM
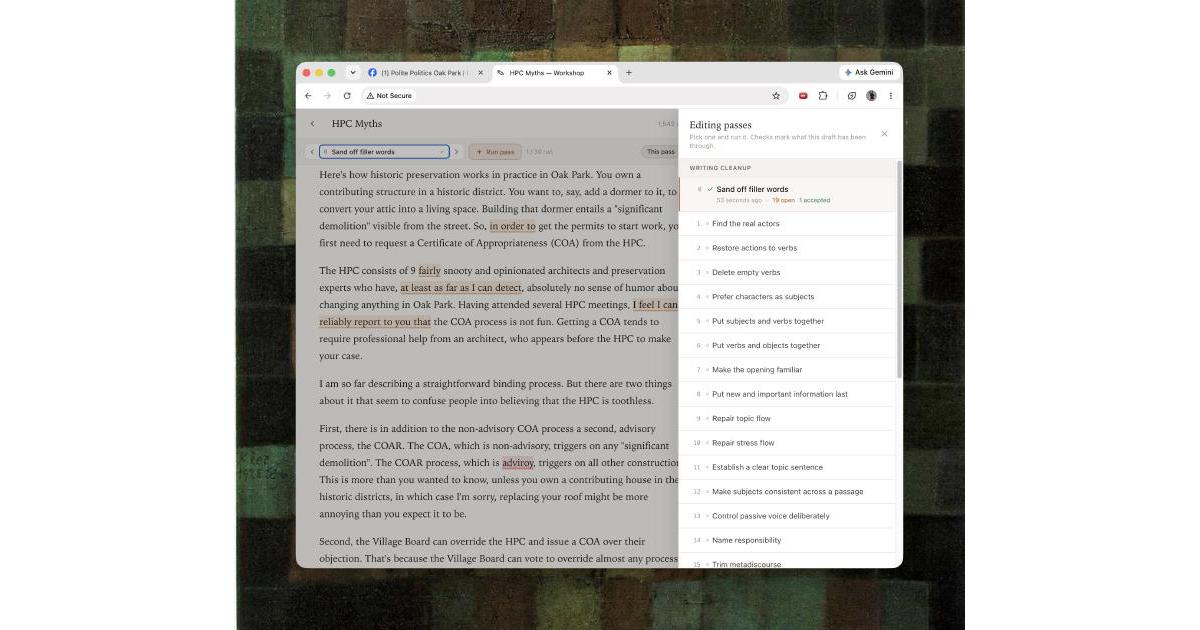
This piece appears to cover approaches to using large language models as writing collaborators, likely including prompting strategies, editing workflows, or voice-preservation tricks. It is a practical, low-technical-depth topic compared to research papers or systems posts, more about applied craft than new technical insight. Its high comment count suggests it sparked debate about authorship and process rather than delivering novel technical content.AI-analyzed
mcncarl/jianying-headless
Jianying is a widely used video editing application, and 'headless' automation of it would let developers script video creation and export without manual UI interaction, useful for content pipelines or bulk editing tasks. The description is sparse, mentioning 'native Jianying drafts,' 'isolated editing/export,' and a 'standalone Agent Skill,' but doesn't clarify how the automation is achieved (e.g., API reverse-engineering, UI scripting) or its reliability. This could be technically interesting to reverse-engineering enthusiasts or media-automation engineers, but the lack of detail and its private-source nature limit broader assessment.AI-analyzed
notablegithubRepoA tool for programmatically driving Jianying (a popular Chinese video editor) in headless mode, useful mainly to a narrow audience doing automated video editing pipelines.TheoLeeCJ/SemIf
The idea of a 'semantic if,' evaluating a conditional branch based on meaning rather than exact value matching, using a locally-run open model on a single consumer GPU (a 3090), is a neat and potentially useful primitive for building AI-infused applications without cloud API costs. The description is terse and doesn't explain implementation details, accuracy, latency, or how it integrates into existing code, which limits how much can be judged. It's positioned as independent from other named projects mentioned elsewhere in this batch ('Jev,' 'TypeSafe'), suggesting a broader ecosystem story not detailed here.AI-analyzed
notablegithubRepoAn intriguing but under-explained concept of using small open-weight language models to implement 'semantic if' conditionals running locally on consumer hardware.Chuloo/mural
Mural appears to be a native iOS app for practicing language learning through conversation, likely powered by some kind of conversational AI. The description is marketing-oriented rather than technical, giving no detail on the underlying model, architecture, or notable engineering approach. Written in Kotlin despite being described as a 'native iPhone' app is a bit odd and worth noting as a possible inconsistency in the provided metadata. Overall this reads more like a product launch than a technical resource for engineers.AI-analyzed
notablegithubRepoA consumer language-learning app for iPhone with a catchy tagline, but not a technically deep or novel engineering project based on the given description.OpenJev
This item only provides a title, 'OpenJev,' with no description or abstract explaining what the project actually does. Given the high engagement, it is likely a notable open-source release, but without more context it's impossible to assess its technical merit. Several other items in this list reference 'Jev,' suggesting it may be a coding-agent or LLM-tooling ecosystem, but this entry alone offers no verifiable detail.AI-analyzed
browser-use/jev-ultrafast
The repo name suggests it's related to the 'browser-use' project, likely some kind of fast browser automation or agent tooling, but the description gives essentially no technical information. High star and fork counts suggest community interest, but without any real description, code details, or documentation excerpt, there's nothing concrete to assess here. This looks like a joke or teaser repository rather than a documented technical release.AI-analyzed
notablegithubRepoA vague repository with no meaningful description ('i. am. speed.') beyond a name suggesting a fast browser-automation tool, offering nothing substantive to evaluate.